P2-4.3 Derivative and Gradient
Section ID:
P2-4.3Version:v2026.09.14
Increasing one parameter may raise the loss while increasing another may lower it. With several adjustable values, one slope is not enough to decide how to change them. A partial derivative measures the rate of change in one variable with the others fixed; the gradient collects these rates into a vector in parameter order.
From One Point to Several Variables
For f(x)=x² in the preceding section, the derivative function f′(x)=2x gives the instantaneous rate at each position, while f′(2)=4 is its value at one position. The number 4 is not an output change itself: it is the limit of the ratio of output change to input change. Increasing the input by 0.01 at x=2 therefore raises the output by approximately 4×0.01=0.04. The actual increase, 2.01²−2²=0.0401, differs slightly from the approximation.
With two inputs, we can calculate a rate along each axis separately. The following simple loss function is constructed to have its smallest value when both parameters are zero.
At the current position [w₁,w₂]=[3,4], the loss is 3²+4²=25. Although there is one loss value, 25, the rates with respect to the two parameters differ.
Partial Derivatives: Change One Variable, Fix the Others
To examine w₁, hold w₂=4 fixed. The function becomes L(w₁,4)=w₁²+16. The term 16 stays constant as w₁ changes, so its derivative is zero, leaving only 2w₁, the derivative of w₁². At the current value w₁=3, this is 6.
Conversely, fixing w₁=3 gives L(3,w₂)=9+w₂². The constant 9 has derivative zero, so the rate with respect to w₂ is 2w₂, which is 8 at the current value w₂=4.
The symbol ∂ is used for partial derivatives. ∂L/∂w₁ denotes the instantaneous rate as w₁ changes with the other variables fixed. We can check its meaning by increasing each parameter separately by 0.01 at the current position.
| Changed parameter | New position | Actual loss increase | Increase approximated using the partial derivative |
|---|---|---|---|
Increase only w₁ | [3.01,4] | 0.0601 | 6×0.01=0.06 |
Increase only w₂ | [3,4.01] | 0.0801 | 8×0.01=0.08 |
For the same small increment, the loss responds more strongly to w₂. Dividing the actual increases by 0.01 gives 6.01 and 8.01. As the increment approaches zero, these ratios approach the partial derivative values 6 and 8.
The Gradient: Collecting Rates into a Vector
The gradient collects the partial derivatives of a scalar-valued function into a vector. The symbol ∇ is read as nabla and denotes the gradient in the following expression.
∇L(w₁,w₂) is a function assigning a vector to each position; ∇L(3,4) is the vector at the current position. Its components follow the parameter order. [6,8] is neither a new parameter setting nor an actual displacement.
When both parameters change slightly, we can approximate the loss change by adding their separate contributions. At the current position, the calculation is:
The centered dot · is the dot product introduced earlier: multiply matching components and add. Increasing both parameters by 0.01 predicts a loss increase of 0.06+0.08=0.14; the actual increase is 3.01²+4.01²−25=0.1402. For a differentiable function, the gradient thus approximates the effect of small simultaneous changes.
Comparing Directions at Equal Distance
To compare directions, first make the travel distances equal. The length of [6,8] is √(6²+8²)=10, so dividing by 10 gives [0.6,0.8], a vector of length 1 pointing in the same direction. Such a vector is called a unit vector. Every direction below has length 1.
Direction u | Dot product ∇L·u | Meaning at the current position |
|---|---|---|
[1,0] | 6 | Instantaneous rate in the direction of increasing w₁ |
[0,1] | 8 | Instantaneous rate in the direction of increasing w₂ |
[0.6,0.8] | 6×0.6+8×0.8=10 | Instantaneous rate in the gradient direction |
[-0.6,-0.8] | −10 | Instantaneous rate opposite the gradient |
∇L·u is the instantaneous rate of change in the function value per unit distance traveled in direction u, called the directional derivative. For example, traveling a distance of 0.01 in direction [0.6,0.8] changes the parameters by [0.006,0.008] and raises the loss by approximately 10×0.01=0.1.
The dot product is largest when the vectors point in the same direction. Thus, for a differentiable function with a nonzero gradient, the gradient direction has the largest instantaneous rate among all unit directions. Here, distance between parameter settings is measured by √(Δw₁²+Δw₂²). Changing parameter units or scales can change the comparison of distances and directions.
Reading Increase and Decrease on Contours
A contour joins positions with the same function value. For L=w₁²+w₂², points equally far from the origin have the same loss, so the contours are circles. The numbers on the circles below are loss values.
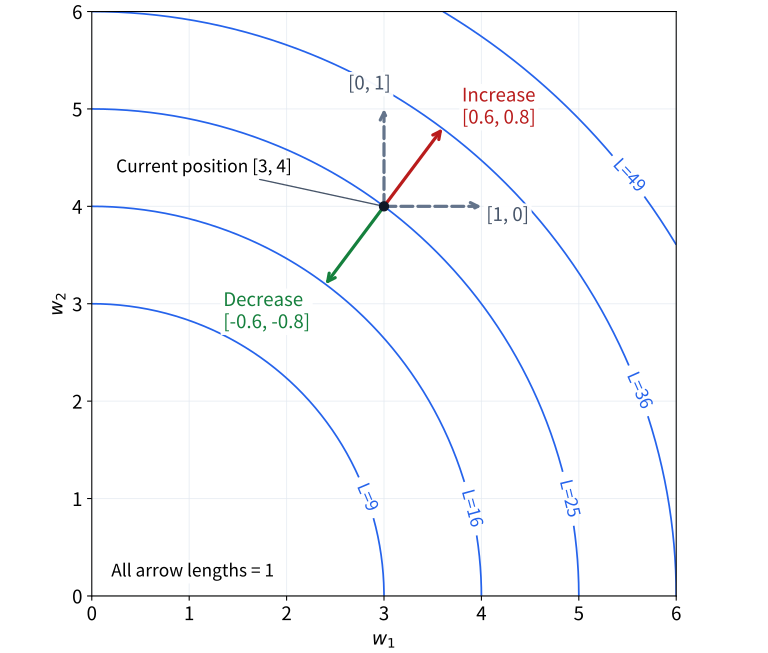
Moving outward from the current point across the blue circles raises the loss; moving inward lowers it. The red arrow shows the gradient direction [0.6,0.8], and the green arrow shows its opposite. The arrows have length 1 to compare directions and do not specify an actual training displacement.
A direction tangent to the circle at the current point is perpendicular to the gradient and has instantaneous rate zero. This does not mean that traveling straight along that tangent preserves the loss. To keep the loss constant, we must continually change direction to follow the circle.
Descent Direction and Step Size
Moving opposite the current gradient [6,8] by 0.01×[6,8] gives the new position [2.94,3.92]. The loss falls from 25 to 24.01. Here, 0.01 is the coefficient multiplying the gradient; the actual distance traveled is 0.01×10=0.1.
Pointing opposite the gradient does not make every large step safe. Starting from the same position with coefficient 1.1 gives [-3.6,-4.8], where the loss increases to 36. Direction information and step size must be distinguished. The next section connects the choice of this coefficient to learning.
A zero gradient means that the first-order rate is zero in every direction, but this alone does not guarantee a minimum. The origin in this example is a minimum; in other functions, a zero gradient can occur at a maximum or a saddle point. At a saddle point, values rise in some directions and fall in others.
Two Weights in a Recommendation Score
Suppose one item has interest similarity 0.8 and freshness 0.4. Multiply these two features by weights w_1 and w_2 to calculate its recommendation score S.
With w_1 = 1 and w_2 = 1, the score is 1.2. Increase one weight by 0.05 while keeping the other fixed.
| Changed weight | New score | Score increase | Increase / 0.05 |
|---|---|---|---|
w_1: 1 → 1.05 | 1.24 | 0.04 | 0.8 |
w_2: 1 → 1.05 | 1.22 | 0.02 | 0.4 |
This expression is linear in each weight, so these rates equal the partial derivatives. The gradient is [0.8, 0.4]. For equal increases in the weights, this item’s score is twice as sensitive to w_1.
This calculation describes the score change for one item. To determine changes in ranking, we must also compare other items’ scores. A higher score does not guarantee a higher click-through rate or greater user satisfaction.
Exercise: Adjusting a Negative Parameter
Change the current position to [-3,4] for the same loss function. First, find the gradient and the unit direction of maximum increase. Second, subtract 0.01 times the gradient from the current position and calculate the new loss. Third, explain how this differs from always decreasing both parameters.
Calculation and Explanation
The gradient is [-6,8], with length 10, so the direction of maximum increase is [-0.6,0.8]. Moving in the opposite direction gives [-3,4]−0.01×[-6,8]=[-2.94,3.92], with loss 24.01. We must increase w₁ and decrease w₂. A descent direction reduces the loss rather than necessarily making every parameter numerically smaller.
Checklist
- Can you distinguish the variable being changed from those held fixed in a partial derivative?
- Can you match gradient components to the parameter order?
- Can you distinguish a partial derivative value from an actual loss change?
- Can you use a dot product to approximate the effect of small simultaneous changes?
- Can you explain why direction comparisons require vectors of equal length?
- Can you distinguish descent direction from displacement and adjust a negative parameter?
Sources and References
- OpenStax, Calculus Volume 1, 3.1 Defining the Derivative. It supports the relation between derivative and instantaneous rate of change. Checked: 2026-09-14.
- OpenStax, Calculus Volume 3, 4.6 Directional Derivatives and the Gradient. It supports partial derivatives, the gradient vector, nabla notation, and the relation between the gradient and the direction of maximum increase. Checked: 2026-09-14.
The numerical examples and contour diagram are original constructions.