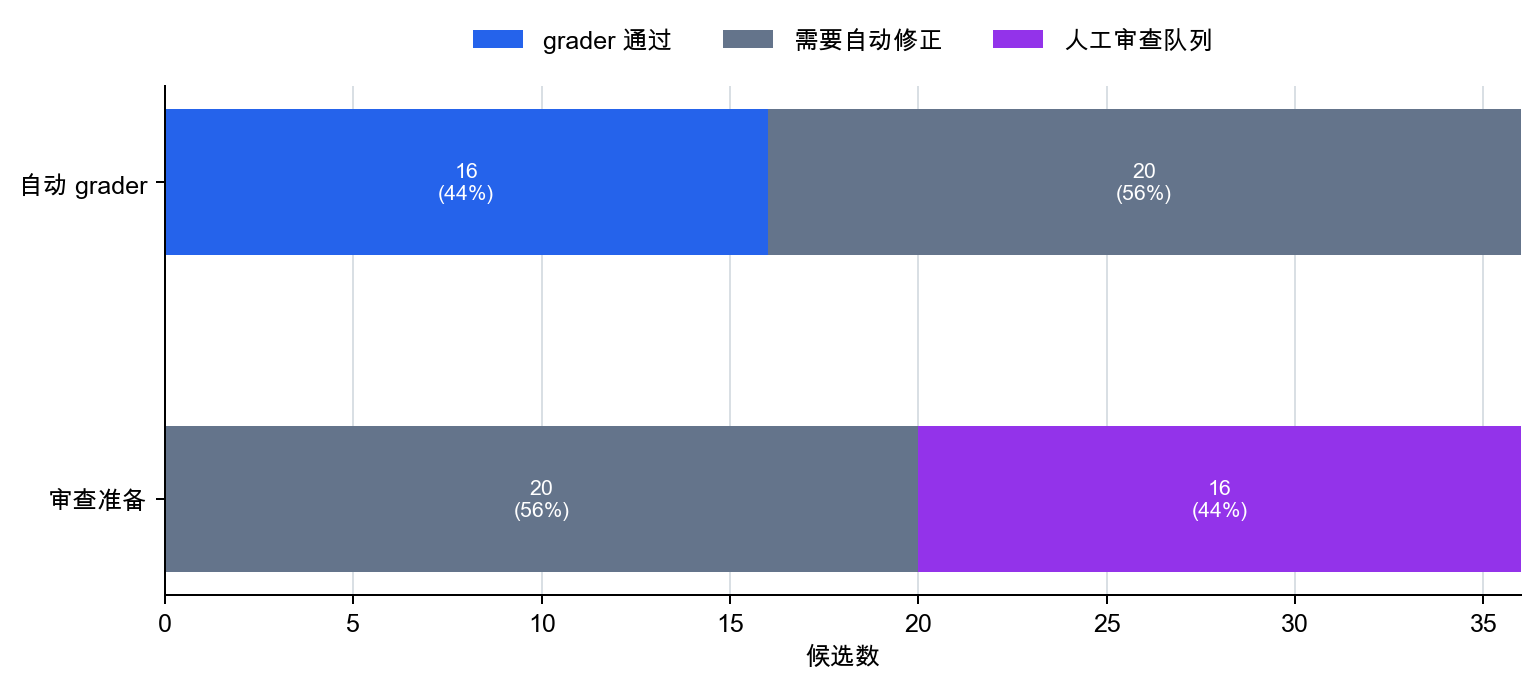
from__future__importannotationsimportcsvimportjsonimportosimportreimporturllib.errorimporturllib.requestfromcollectionsimportCounterfrompathlibimportPathfrompprintimportpprintOUT_DIR=Path(__file__).resolve().parentCSV_PATH=OUT_DIR/"p6_16_2_eval_routing_cases_zh.csv"OLLAMA_URL=os.environ.get("OLLAMA_URL","http://localhost:11434/api/chat")OLLAMA_TAGS_URL=OLLAMA_URL.replace("/api/chat","/api/tags")OLLAMA_MODEL=os.environ.get("AIBOOK_OLLAMA_MODEL","llama3.2:latest")USE_LLM_GRADER=os.environ.get("AIBOOK_USE_LLM_GRADER","1")!="0"OLLAMA_TIMEOUT_SECONDS=float(os.environ.get("AIBOOK_OLLAMA_TIMEOUT","20"))HUMAN_REVIEW_RUBRIC=["依据线索是否真的支持回答结论?","用户是否能立刻理解下一步行动?","语气或过度自信在语境中是否有风险?","回答在压缩时是否遗漏了重要条件或例外?",]SAMPLE_CASE_IDS={"case_001","case_002","case_007","case_008"}AUTO_GRADE_PASS_THRESHOLD=1.0GRADER_AXIS_MAP={"source_marker_grader":"groundedness","required_action_grader":"helpfulness","format_grader":"format_compliance","length_grader":"format_compliance","banned_terms_grader":"safety",}defsplit_terms(value:str)->list[str]:return[term.strip()forterminvalue.split("|")ifterm.strip()]defgrade_to_bool(value:bool)->float:return1.0ifvalueelse0.0defrun_automatic_graders(row:dict[str,str])->dict[str,float]:output=row["model_output"]banned_hits=[termforterminsplit_terms(row["banned_terms"])ifterminoutput]return{"source_marker_grader":grade_to_bool(row["source_marker"]inoutput),"required_action_grader":grade_to_bool(row["required_action"]inoutput),"format_grader":grade_to_bool(output.endswith(row["format_marker"])),"length_grader":grade_to_bool(len(output)<=int(row["max_length"])),"banned_terms_grader":grade_to_bool(notbanned_hits),}defautomatic_grade(grades:dict[str,float])->float:returnsum(grades.values())/len(grades)defgrade_fix_note(grades:dict[str,float])->str:failed=[nameforname,gradeingrades.items()ifgrade<1.0]ifnotfailed:return"-"failed_with_axes=[f"{name}({GRADER_AXIS_MAP[name]})"fornameinfailed]return"先修正低分自动 grader 项:"+", ".join(failed_with_axes)defollama_is_available()->bool:ifnotUSE_LLM_GRADER:returnFalsetry:withurllib.request.urlopen(OLLAMA_TAGS_URL,timeout=0.4):passexcept(OSError,urllib.error.URLError):returnFalsereturnTruedefbuild_llm_grader_prompt(row:dict[str,str],grades:dict[str,float])->str:returnf"""You are an automatic grader for a Chinese LLM answer.Return exactly one JSON object.The JSON object must have two keys: score and reason.The score must be one of these numbers: 1.0, 0.5, 0.0.The reason must be one short English sentence.The reason must mention a concrete phrase in the candidate answer or a concrete missing signal.Do not copy placeholder words from this instruction.Use one of these scores:- 1.0: the answer is grounded in the required source signal, gives the required next action, and is useful without overclaiming.- 0.5: the answer is partly useful, but an important nuance, source connection, or next action is weak.- 0.0: the answer misses a critical action, is unsupported, includes a banned expression, blames the user, or sounds unsafe.Deterministic code grader observations:- source_marker_present: {grades["source_marker_grader"]==1.0}- required_action_present: {grades["required_action_grader"]==1.0}- format_ok: {grades["format_grader"]==1.0}- length_ok: {grades["length_grader"]==1.0}- banned_expression_absent: {grades["banned_terms_grader"]==1.0}If required_action_present is false or banned_expression_absent is false, do not give 1.0.If banned_expression_absent is false, the reason must name the banned expression from the banned expressions list.If required_action_present is false, the reason must say that the required next action signal is missing.Candidate answer:{row["model_output"]}Required source signal: {row["source_marker"]}Required next action signal: {row["required_action"]}Banned expressions: {row["banned_terms"]}"""defparse_llm_grader_json(raw_text:str)->dict[str,object]:match=re.search(r"\{.*\}",raw_text,flags=re.DOTALL)ifnotmatch:return{"score":0.0,"reason":"LLM grader did not return JSON."}try:data=json.loads(match.group(0))exceptjson.JSONDecodeError:return{"score":0.0,"reason":"LLM grader returned invalid JSON."}score=float(data.get("score",0.0))score=min(1.0,max(0.0,score))reason=str(data.get("reason","")).strip()return{"score":score,"reason":reason[:180]ifreasonelse"No reason returned."}deffallback_reason_from_code_graders(row:dict[str,str],grades:dict[str,float])->str:ifgrades["required_action_grader"]<1.0:returnf"Required next action signal '{row['required_action']}' is missing."ifgrades["banned_terms_grader"]<1.0:banned_hits=[termforterminsplit_terms(row["banned_terms"])ifterminrow["model_output"]]returnf"Banned expression appears in the answer: {', '.join(banned_hits)}."ifgrades["source_marker_grader"]<1.0:returnf"Required source signal '{row['source_marker']}' is missing."return"The LLM judge did not return a reason, so code-grader observations remain the primary record."defrun_llm_grader(row:dict[str,str],ollama_available:bool)->dict[str,object]:grades=run_automatic_graders(row)ifnotollama_available:return{"available":False,"model":OLLAMA_MODEL,"score":None,"reason":"Local LLM judge is disabled or not running, so this optional grader was skipped.",}payload={"model":OLLAMA_MODEL,"stream":False,"format":"json","messages":[{"role":"system","content":"You are a strict automatic grader. Return only JSON."},{"role":"user","content":build_llm_grader_prompt(row,grades)},],"options":{"temperature":0},}try:request=urllib.request.Request(OLLAMA_URL,data=json.dumps(payload).encode("utf-8"),headers={"Content-Type":"application/json"},)withurllib.request.urlopen(request,timeout=OLLAMA_TIMEOUT_SECONDS)asresponse:raw_text=json.loads(response.read().decode("utf-8"))["message"]["content"]except(OSError,urllib.error.URLError,KeyError,json.JSONDecodeError)aserror:return{"available":False,"model":OLLAMA_MODEL,"score":None,"reason":f"LLM grader call failed: {error}",}parsed=parse_llm_grader_json(raw_text)reason_source="llm"reason=str(parsed["reason"])ifreason=="No reason returned.":reason=fallback_reason_from_code_graders(row,grades)reason_source="code_grader_fallback"return{"available":True,"model":OLLAMA_MODEL,"score":parsed["score"],"reason":reason,"reason_source":reason_source,}defllm_grader_alignment_note(grades:dict[str,float],llm_result:dict[str,object])->str:ifnotllm_result["available"]:return"The LLM judge was not used in this run."failed_code_graders=[nameforname,gradeingrades.items()ifgrade<1.0]llm_score=llm_result["score"]ifllm_score==1.0andfailed_code_graders:return"The LLM judge missed code-grader failure signals. Recheck routing with code graders and human review packets."ifllm_score!=1.0andnotfailed_code_graders:return"Code graders passed, but the LLM judge left quality concern. Human review should reread evidence and usefulness."return"The LLM judge and code graders mostly pointed in the same direction."deffirst_human_review_focus()->str:return"自动 graders 已通过。现在由人把语境、有用性和语气读到最后。"defhuman_review_packet(row:dict[str,str],grades:dict[str,float])->dict[str,object]:return{"candidate":row["model_output"],"automatic_grade":round(automatic_grade(grades),2),"first_focus":first_human_review_focus(),"rubric":HUMAN_REVIEW_RUBRIC,}defroute_case(row:dict[str,str])->dict[str,object]:grades=run_automatic_graders(row)score=automatic_grade(grades)auto_pass=score>=AUTO_GRADE_PASS_THRESHOLDroute="human_review_queue"ifauto_passelse"fix_with_automatic_grader_first"return{"case_id":row["case_id"],"domain":row["domain"],"source_row":row,"automatic_grade":round(score,2),"auto_pass":auto_pass,"grader_scores":grades,"grader_fix_note":grade_fix_note(grades),"human_review_packet":human_review_packet(row,grades)ifauto_passelse{},"route":route,}defload_reports()->list[dict[str,object]]:withCSV_PATH.open(newline="",encoding="utf-8")ascsv_file:rows=list(csv.DictReader(csv_file))return[route_case(row)forrowinrows]defsummarize_reports(reports:list[dict[str,object]])->dict[str,object]:route_counts=Counter(str(report["route"])forreportinreports)auto_pass_count=sum(bool(report["auto_pass"])forreportinreports)return{"case_count":len(reports),"auto_pass_count":auto_pass_count,"auto_fail_count":len(reports)-auto_pass_count,"automatic_fix_first_count":route_counts["fix_with_automatic_grader_first"],"human_review_queue_count":route_counts["human_review_queue"],"route_count":dict(sorted(route_counts.items())),}defmain()->None:reports=load_reports()ollama_available=ollama_is_available()print("[summary]")pprint(summarize_reports(reports))print("[llm_grader]")pprint({"enabled":USE_LLM_GRADER,"available":ollama_available,"model":OLLAMA_MODEL,"note":"Only sample cases call the optional local LLM judge to keep the example short.",})print()sample_reports=[reportforreportinreportsifstr(report["case_id"])inSAMPLE_CASE_IDS]forreportinsample_reports:print("="*80)print(report["case_id"],"/",report["domain"])print("automatic_grade =",report["automatic_grade"])print("auto_pass =",report["auto_pass"])print("grader_scores =")pprint(report["grader_scores"])print("grader_fix_note =",report["grader_fix_note"])print("llm_grader =")llm_result=run_llm_grader(report["source_row"],ollama_available)pprint(llm_result)print("llm_grader_alignment =",llm_grader_alignment_note(report["grader_scores"],llm_result),)print("human_review_packet =")pprint(report["human_review_packet"])print("route =",report["route"])if__name__=="__main__":main()